👋 About Me
Hi! I’m Hanke Xie (解晗轲), a second-year master’s student at Northwestern Polytechnical University (NPU). I am a member of the Audio, Speech and Language Processing Group (ASLP@NPU), advised by Prof. Lei Xie. I received my Bachelor’s degree in Artificial Intelligence from the School of Computer Science at NPU in 2025.
My research focuses on speech generation and spoken interaction, including text-to-speech, singing voice synthesis, and LLM-based spoken dialogue systems. My recent work spans zero-shot TTS, long-form conversational and podcast speech generation, low-latency streaming TTS, and continuous-latent speech generation.
🔥 News
- 2026.10: 🎉 The inference code and checkpoints of SemBridge are released!
- 2026.09: 🎉 X-Pred MeanFlow is accepted by ISCSLP 2026.
- 2026.08: 📄 SemBridge is released on arXiv.
- 2026.06: 🎉 FlashTTS is accepted by Interspeech 2026.
- 2025.10: 🚀 SoulX-Podcast is open-sourced, supporting 90+ minutes of multi-speaker podcast generation with dialects and paralinguistics.
📝 Publications
For the most up-to-date publication list, please visit my Google Scholar profile. (* indicates equal contribution)
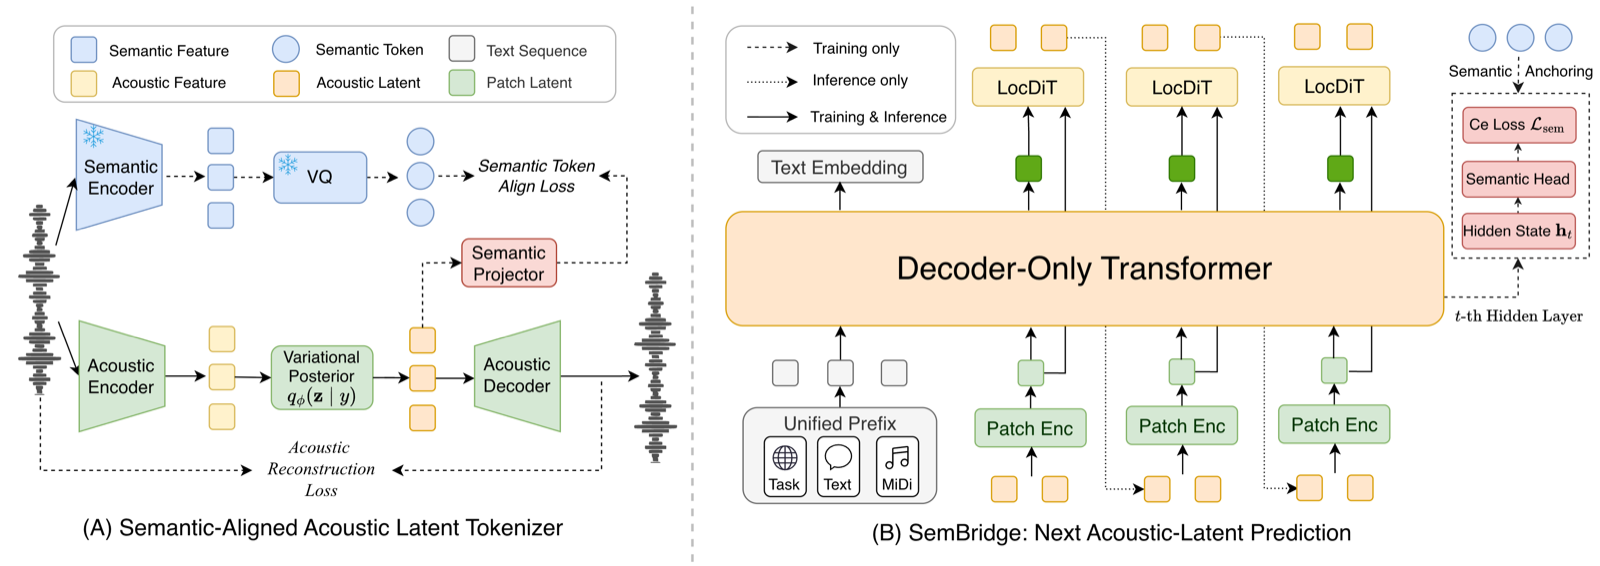
SemBridge: Semantic Token Anchoring for Continuous-Latent Autoregressive Speech Generation
Hanke Xie, Haopeng Lin, Jiale Qian, Dake Guo, Yuepeng Jiang, Zhichao Wang, Wenxiao Cao, Jingbin Hu, Guobin Ma, Wenhao Li, Huakang Chen, Chengyou Wang, Ming Tao, Zhonghua Fu, Lei Xie, Xinsheng Wang

- A training-only semantic-token anchoring framework that directly supervises the states of a continuous-latent AR language model with discrete semantic tokens, while inference remains entirely continuous.
- Consistently improves content accuracy (WER/CER) on both zero-shot TTS and score-conditioned singing voice synthesis.
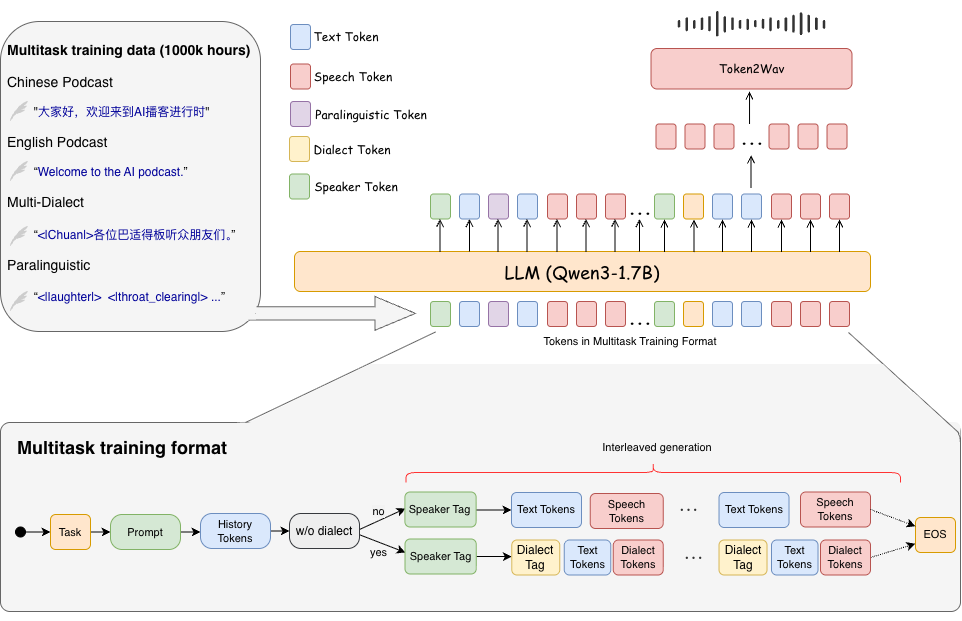
SoulX-Podcast: Towards Realistic Long-form Podcasts with Dialectal and Paralinguistic Diversity
Hanke Xie*, Haopeng Lin*, Wenxiao Cao, Dake Guo, Wenjie Tian, Jun Wu, Hanlin Wen, Ruixuan Shang, Hongmei Liu, Zhiqi Jiang, Yuepeng Jiang, Wenxi Chen, Ruiqi Yan, Jiale Qian, Yichao Yan, Shunshun Yin, Ming Tao, Xie Chen, Lei Xie, Xinsheng Wang

- A podcast-style multi-turn, multi-speaker dialogue speech generation system with paralinguistic controls, supporting Mandarin, English and Chinese dialects (Sichuanese, Henanese and Cantonese).
- Continuously generates over 90 minutes of conversation with stable speaker timbre and smooth speaker transitions.
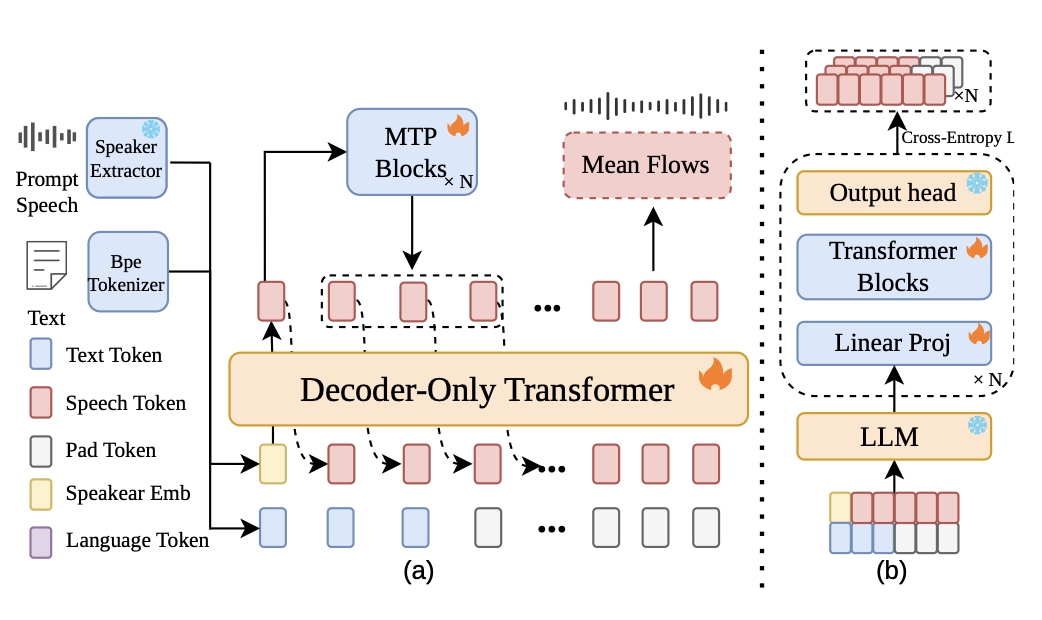
FlashTTS: Fast Streaming TTS with MTP Acceleration and X-pred Mean Flow Distillation
Hanke Xie, Xiaming Ren, Dake Guo, Ruonan You, Wenhao Li, Jingbin Hu, Guobin Ma, Huakang Chen, Kejie Xu, Rui Huang, Weiguo Tan, Xianrong Wang, Lei Xie

- An open-source low-latency streaming TTS framework with a lagged multi-track architecture for native streaming text/speech input, parallel Multi-Token Prediction (MTP), and a 2-NFE X-pred mean-flow decoder.
- Reduces first-packet latency to 325 ms while preserving strong zero-shot voice cloning.
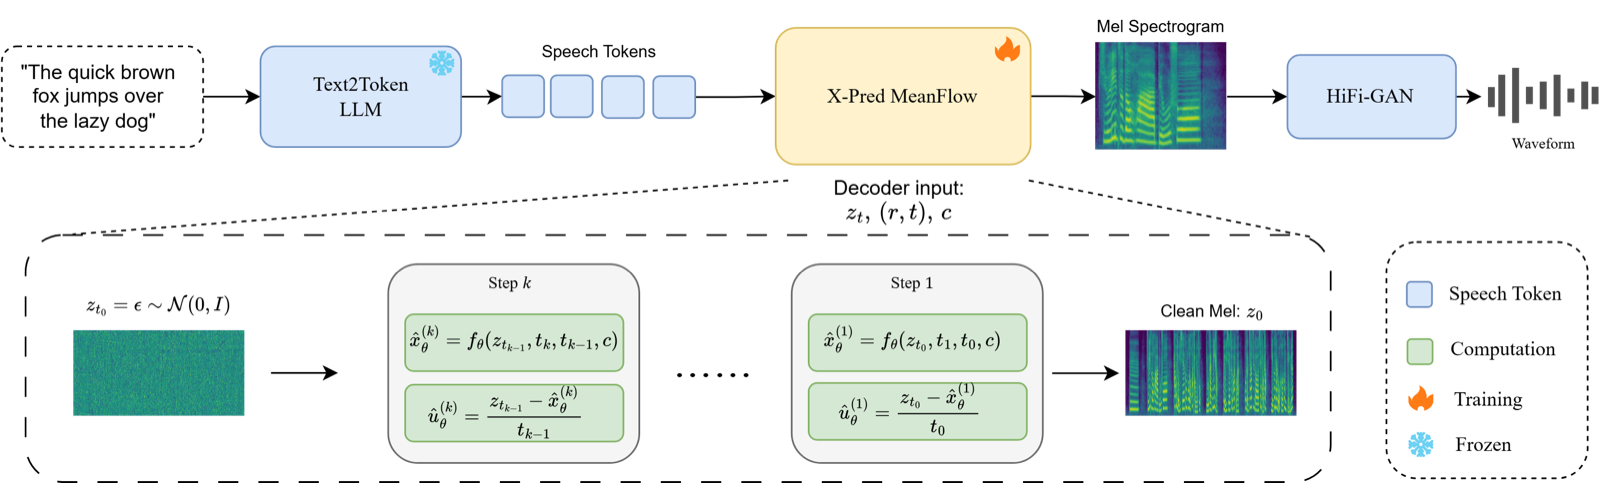
X-Pred MeanFlow for Streaming Token-to-Mel Speech Decoding
Hanke Xie, Xiaming Ren, Qirui Zhan, Jingbin Hu, Wenhao Li, Haoyu Zhang, Ruonan You, Chengyou Wang, Yunxiang Chen, Houdun Liu, Su Feng, Lei Xie
- A few-step streaming token-to-mel decoder that reparameterizes MeanFlow with mel-space prediction, together with layer-selective block-wise attention for chunk-wise streaming generation.
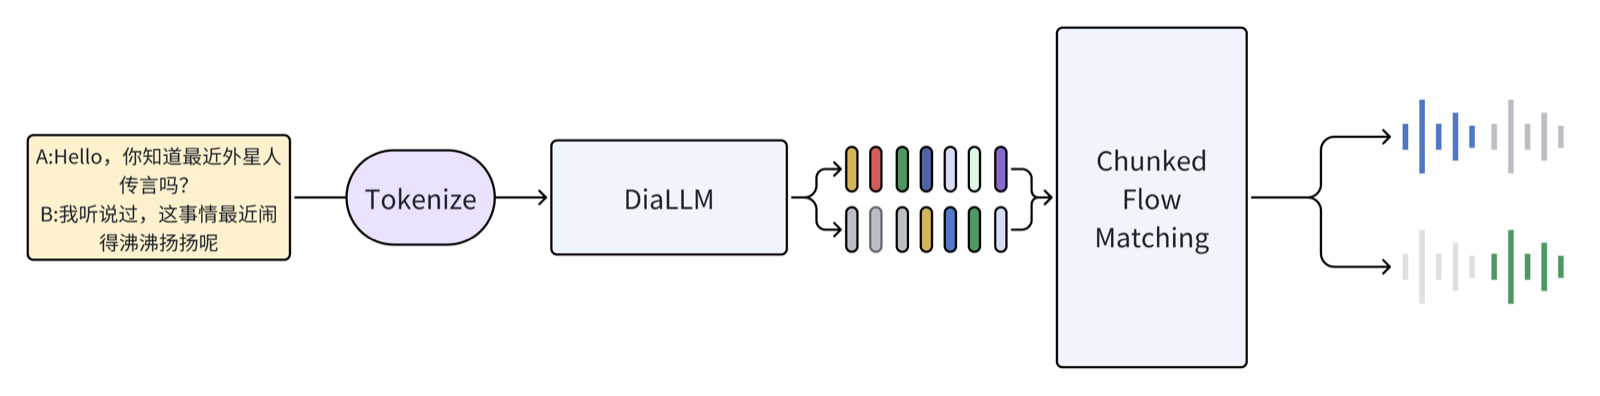
DialoSpeech: Dual-Speaker Dialogue Generation with LLM and Flow Matching
Hanke Xie, Dake Guo, Chengyou Wang, Yue Li, Wenjie Tian, Xinfa Zhu, Xinsheng Wang, Xiulin Li, Guanqiong Miao, Bo Liu, Lei Xie
- A dual-track architecture combining an LLM with chunked flow matching for human-like dual-speaker dialogue generation with coherent turn-taking and natural overlaps, plus a pipeline for building dual-track dialogue data.
ACM MM 2026MINT-Bench: A Comprehensive Multilingual Benchmark for Instruction-Following Text-to-Speech, Huakang Chen, Jingbin Hu, Liumeng Xue, Qirui Zhan, Wenhao Li, Guobin Ma, Hanke Xie, Dake Guo, Linhan Ma, Yuepeng Jiang, Bengu Wu, Pengyuan Xie, Chuan Xie, Qiang Zhang, Lei Xie.Tech ReportSoulX-Singer: Towards High-Quality Zero-Shot Singing Voice Synthesis, Jiale Qian, Hao Meng, Tian Zheng, Pengcheng Zhu, Haopeng Lin, Yuhang Dai, Hanke Xie, Wenxiao Cao, Ruixuan Shang, Jun Wu, Hongmei Liu, Hanlin Wen, Jian Zhao, Zhonglin Jiang, Yong Chen, Shunshun Yin, Ming Tao, Jianguo Wei, Lei Xie, Xinsheng Wang.Tech ReportOSUM-EChat: Enhancing End-to-End Empathetic Spoken Chatbot via Understanding-Driven Spoken Dialogue, Xuelong Geng, Qijie Shao, Hongfei Xue, Shuiyuan Wang, Hanke Xie, Zhao Guo, Yi Zhao, Guojian Li, Wenjie Tian, Chengyou Wang, Zhixian Zhao, Kangxiang Xia, Ziyu Zhang, Zhennan Lin, Tianlun Zuo, Mingchen Shao, Yuang Cao, Guobin Ma, Longhao Li, Yuhang Dai, Dehui Gao, Dake Guo, Lei Xie.
🎖 Honors and Awards
- 2025.06, Outstanding Graduate of Northwestern Polytechnical University (Top 10%).
- 2021 - 2024, Outstanding Student of Northwestern Polytechnical University (Top 10%), three consecutive years (2021-2022, 2022-2023, 2023-2024).
📖 Educations
- 2025.09 - Present, M.Eng. in Software Engineering (exempted from the entrance exam), School of Software, Northwestern Polytechnical University, Xi’an. Member of ASLP@NPU, advised by Prof. Lei Xie.
- 2021.09 - 2025.06, B.Eng. in Artificial Intelligence (Top 10%), School of Computer Science, Northwestern Polytechnical University, Xi’an.
💻 Internships
- 2026.09 - Present, Tencent Hunyuan, Speech Team, Beijing, China.
- 2025.07 - 2026.07, Soul App, Soul AI Lab, Multimodal Interaction Group, Shanghai, China. Co-advised by Haopeng Lin and Xinsheng Wang.